
evaluation
-
Mobile Development
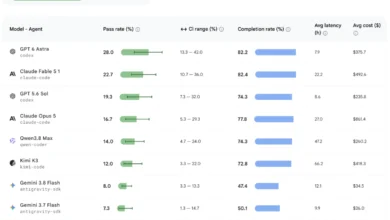
Android Bench 2.0 Launches to Revolutionize AI Development Evaluation with Long-Horizon Task Benchmarking
The landscape of software development is undergoing a seismic shift as artificial intelligence transitions from simple code-completion tools to autonomous,…
Read More » -
Mobile Development
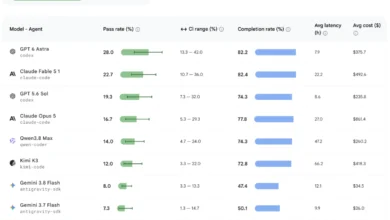
Android Bench 2.0 Launches to Revolutionize AI Evaluation for Long-Horizon Android Development Tasks
The rapid advancement of artificial intelligence in software engineering has necessitated a fundamental shift in how developers measure the efficacy…
Read More » -
Artificial Intelligence
LLM Evaluation Frameworks Compared: How to Actually Measure What Your Model Does
The rapid deployment of Large Language Model (LLM) applications has introduced a novel set of challenges for quality assurance, distinct…
Read More » -
Mobile Development
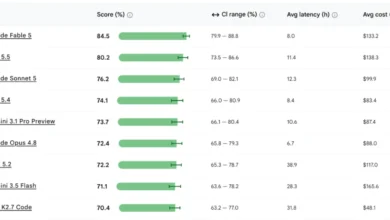
Android Bench Enhances AI Evaluation for Developers with Harbor Framework Integration and Community Contributions
Android Bench, the pioneering leaderboard designed to assess Large Language Models (LLMs) on real-world Android development tasks, has undergone a…
Read More »
