Bridging the Gap Between Demo and Production: Understanding the AI Agent Harness and Architectural Frameworks

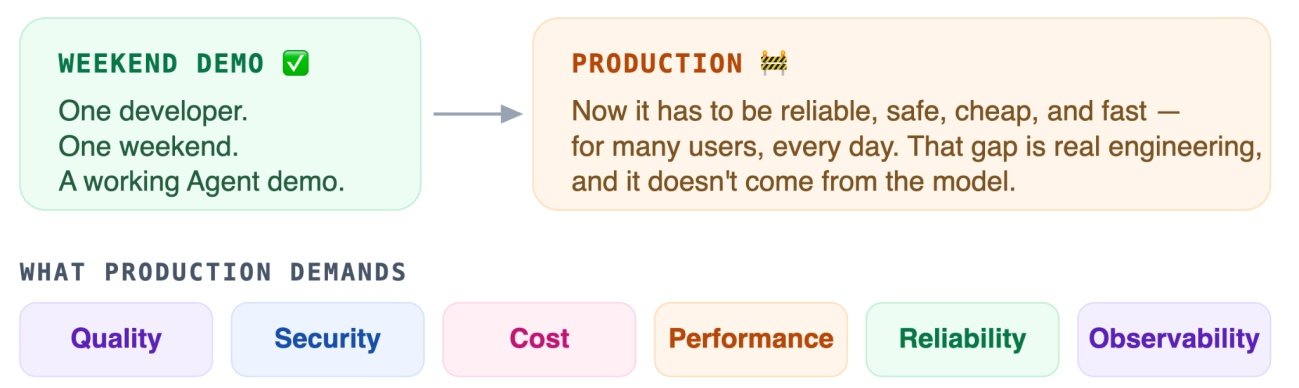
The rapid evolution of generative artificial intelligence has fundamentally altered the software development landscape, shifting the primary bottleneck from foundational model capabilities to production-grade reliability. While spinning up a proof-of-concept AI agent can typically be accomplished within a single afternoon, engineering a system that remains operational, secure, cost-effective, and transparent under real-world enterprise conditions presents a significantly greater technical challenge. Industry data indicates that production readiness relies less on the underlying language model and more on the surrounding infrastructure—encompassing memory management, tool access, model routing, guardrails, cost controls, and observability traces. This surrounding structural layer is formally defined as the agent harness.
The Evolution of Agent Architecture and the Harness Concept
Although the terminology surrounding the "agent harness" has gained widespread adoption recently, the engineering practices defining it have matured organically alongside the deployment of autonomous systems. In previous developmental phases, engineering teams manually integrated tools, hard-coded prompt sequences, and patched execution failures reactively. Standardizing this architecture under the umbrella of the agent harness allows organizations to treat reliability, security, and operational visibility as deliberate design parameters rather than reactive, one-off patches.
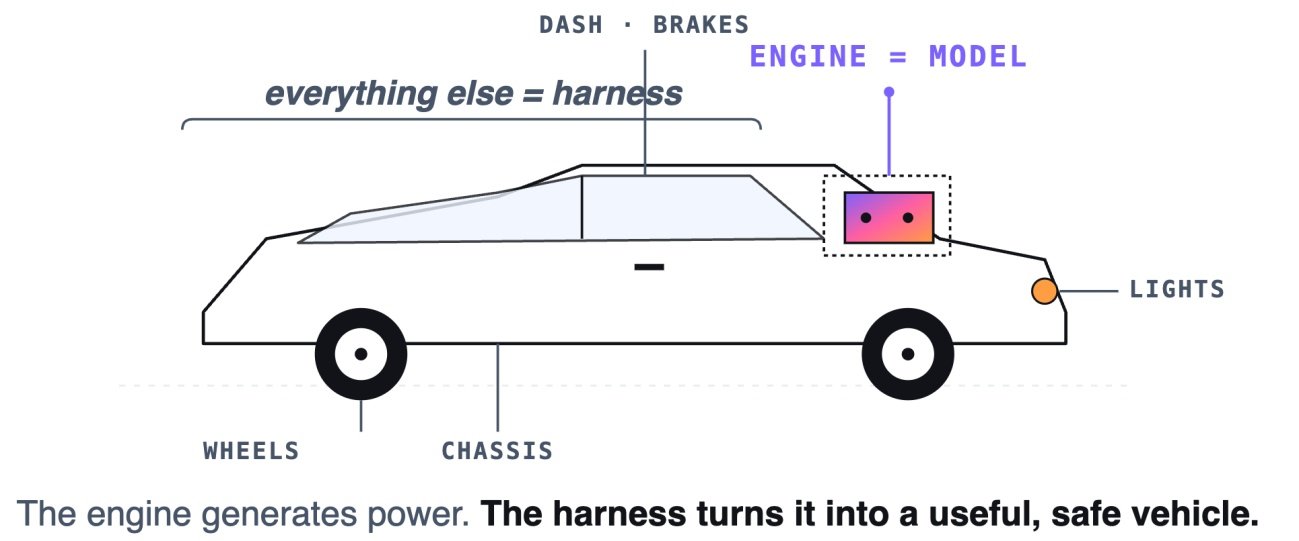
Drawing from established architectural frameworks, an autonomous agent can be conceptualized as a combination of a powerful computational engine—the model—and a robust chassis—the harness. Analogous to an automotive vehicle where the internal combustion engine generates raw power, the braking systems, chassis, steering mechanics, and safety features determine whether the vehicle is suitable for commercial deployment. Similarly, the foundational model executes high-level cognitive tasks, while the harness ensures safety, deterministic execution, structured tool usage, and predictable cost management.
The Two Halves of an Agent Harness: Development and Operations
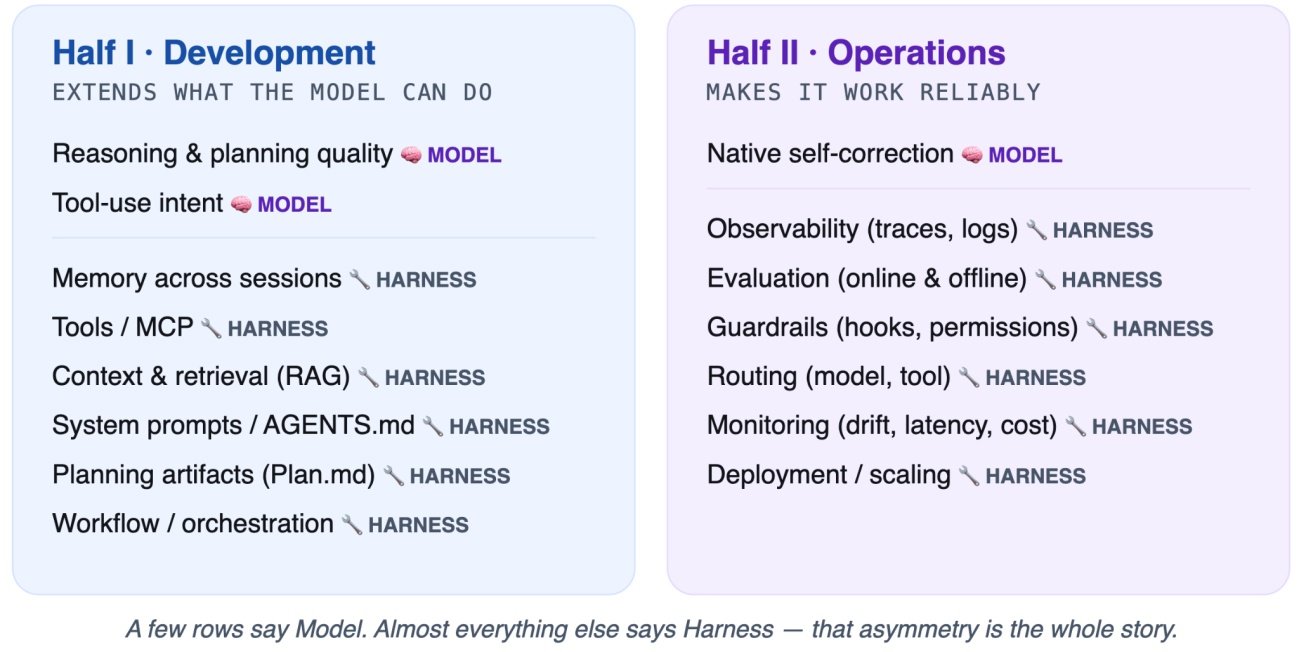
Architecturally, the components of an agent harness divide into two distinct functional categories: development and operations.
The development domain focuses on expanding the functional reach of the model. This includes maintaining cross-session memory, integrating external tools via protocols such as the Model Context Protocol (MCP), executing Retrieval-Augmented Generation (RAG) over proprietary data stores, managing prompt engineering, and orchestrating multi-step execution graphs.
Conversely, the operational domain governs runtime stability, governance, and lifecycle management under live user traffic. This operational layer closely mirrors traditional DevOps principles, encompassing distributed observability, automated evaluation frameworks, request guardrails, multi-provider model routing, drift and cost monitoring, as well as deployment scaling. While a stronger foundational model enhances overall performance, the operational resilience of the agent depends entirely on the maturity of its surrounding harness.
Strategic Implementation Paradigms: Harness-as-a-Service vs. Self-Managed Stacks
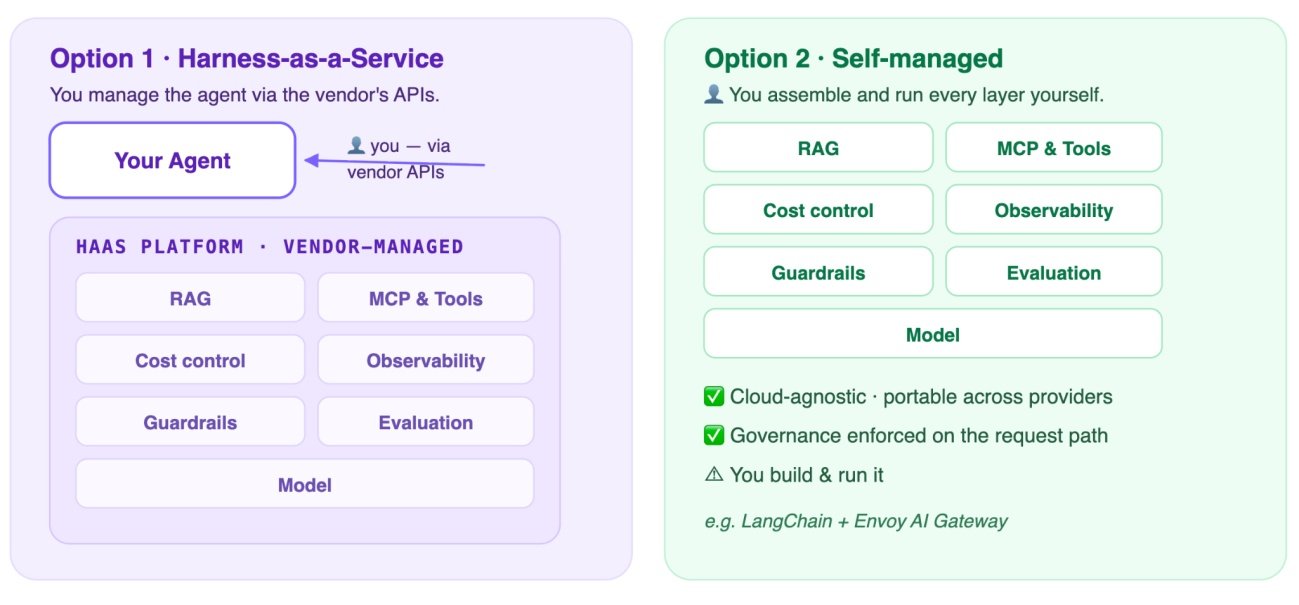
When architecting a production-grade agent, engineering teams typically choose between two primary operational methodologies: Harness-as-a-Service (HaaS) and self-managed infrastructure stacks. Both models utilize identical underlying primitives—including model access layers, semantic retrieval, tool execution environments, and guardrails—but package these capabilities differently, impacting delivery speed, infrastructure control, and operational expenditure.
Harness-as-a-Service platforms, such as AWS AgentCore, Google Vertex AI Agent Engine, Azure AI Foundry Agent Service, and LangGraph Platform, provide vendor-managed runtimes that expose the entire development and operational harness via managed APIs. This approach allows enterprises to accelerate time-to-market by offloading infrastructure maintenance, scaling, and native tracing to the cloud provider. However, organizations remain responsible for defining policies, financial budgets, prompt schemas, tool definitions, and evaluation frameworks.
In contrast, self-managed architectures empower engineering teams to assemble the harness using software development kits and open-source components deployed across container orchestration platforms like Kubernetes. Utilizing tools such as LangChain, LlamaIndex, and dedicated routing layers like Agent Router (formerly Envoy AI Gateway) and LiteLLM, organizations retain complete architectural ownership, multi-cloud portability, and granular configuration control. This approach trades the convenience of managed services for direct responsibility over deployment lifecycles, software upgrades, and on-call incident management.
Case Study: Architecting FinBot for Production Deployment
To illustrate the practical differences between these paradigms, consider the deployment of "FinBot," a financial analysis agent designed to process natural language inquiries regarding corporate financial performance. When a user requests a summary of third-quarter revenue, FinBot must retrieve relevant regulatory filings from a document store, delegate numeric computations to a secure code interpreter, synthesize the data via an LLM, and return a validated response.
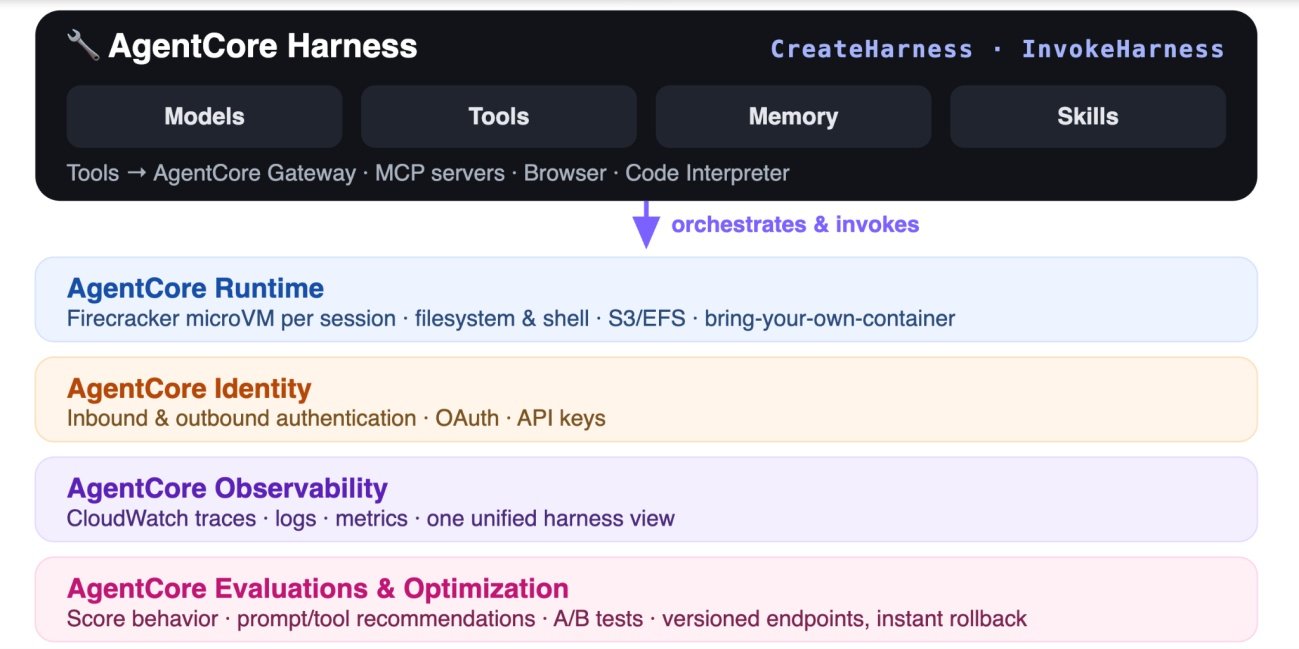
In a fully managed HaaS implementation utilizing AWS AgentCore, the agent is configured through declarative control-plane APIs. The underlying runtime automatically provisions isolated execution environments—such as Firecracker microVMs per session—manages semantic memory persistence, assigns identity through token vaults, and streams distributed telemetry to CloudWatch. System prompts, remote MCP tool integrations, and retrieval targets are instantiated through high-level configuration objects, minimizing boilerplate infrastructure code.
Alternatively, a self-managed deployment architecture configures FinBot as a standard LangChain application communicating through an Envoy-based AI Gateway deployed within a Kubernetes cluster. In this setup, the gateway acts as a unified front door for disparate model providers, executing token-based rate limiting, dynamic request routing, failover protocols, and security enforcement before forwarding requests upstream. Session persistence is maintained via asynchronous PostgreSQL checkpointers, while tools and vector retrieval engines are coordinated directly within the application code.
Operational Capabilities: Cost Control, Model Routing, and Observability
Regardless of the architectural paradigm selected, production environments demand rigorous controls across three critical operational pillars: model access, cost containment, and observability.
Unified Model Access Simplification
Multi-provider environments often introduce complexity due to fragmented software development kits, authentication mechanisms, and response schemas. A centralized gateway or managed runtime abstracts these disparities, enabling organizations to implement model updates, canary deployments, or automatic failovers through configuration adjustments rather than application code modifications. In self-managed environments, cryptographic credentials are securely managed via cloud-native identity policies, such as AWS Pod Identity or IAM Roles for Service Accounts (IRSA), eliminating static API keys from application memory.
Granular Cost Control Mechanisms
Uncontrolled agent loops or inefficient prompt designs can rapidly inflate operational expenditures through excessive token consumption. Production harnesses mitigate this risk by enforcing deterministic runtime limits, such as maximum iteration caps and hard timeout thresholds. Furthermore, distributed gateways implement policy-driven token budgets per tenant or user session, automatically terminating runaway execution cycles or rejecting requests exceeding daily allocations with standard HTTP 429 rate-limit responses.
Comprehensive Distributed Observability
Because autonomous agents function as non-deterministic black boxes, distributed tracing is essential for root-cause analysis during production incidents. Managed platforms incorporate native telemetry pipelines that automatically capture prompt-to-response chains, latency metrics, and tool execution logs. Similarly, open-source stacks leverage OpenTelemetry semantic conventions (gen_ai.*) to standardize telemetry data across diverse model providers, allowing unified collectors to aggregate traces into backends like Langfuse, Phoenix, or OpenLIT. This granular visibility enables engineering teams to monitor token expenditure, trace multi-step reasoning paths, and isolate performance bottlenecks during high-volume operations.
Industry Implications and Future Outlook
The formalization of the agent harness as a discrete architectural layer represents a maturation milestone in the enterprise adoption of artificial intelligence. As organizations transition from exploratory proof-of-concept projects to mission-critical deployments, the competitive advantage will increasingly lie in robust operational governance rather than raw model capabilities alone.
Industry analysts emphasize that successful AI integration requires striking an optimal balance between velocity and control. Whether organizations leverage fully managed cloud services to accelerate deployment or build self-managed Kubernetes stacks to preserve infrastructure independence, the foundational principles remain constant. By establishing rigorous guardrails, deterministic execution limits, and comprehensive observability, enterprises can transform probabilistic language models into reliable, production-ready software systems capable of operating autonomously at scale.