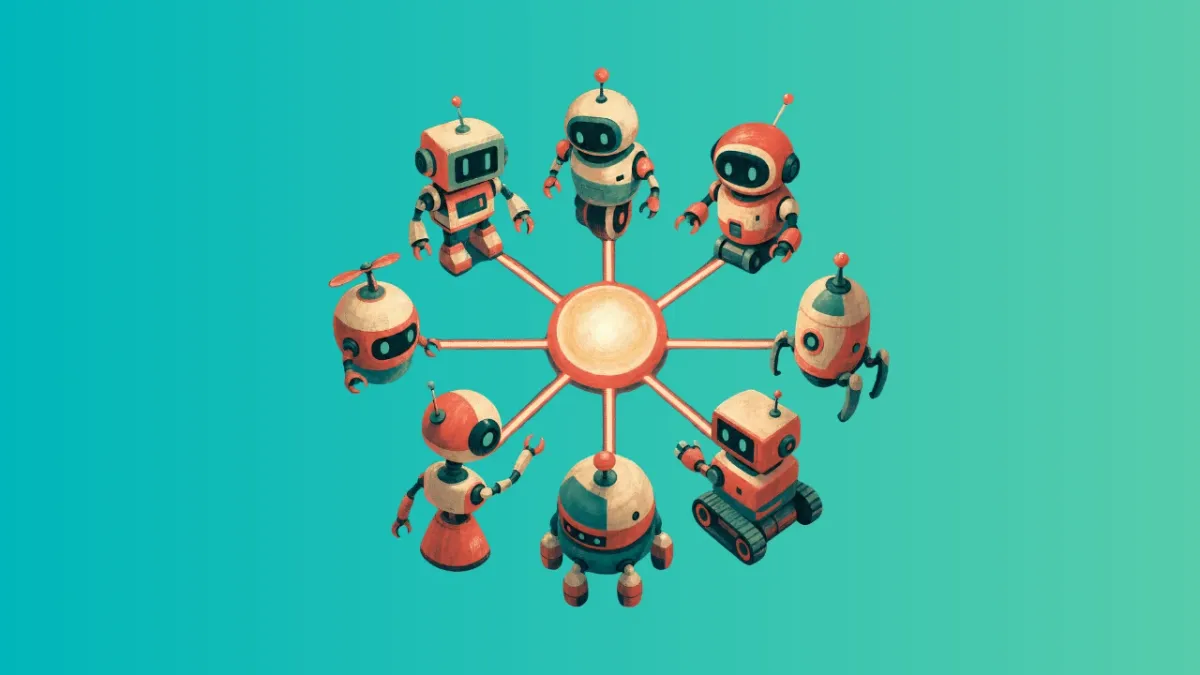
The rapid evolution of local artificial intelligence has entered a new phase characterized by the transition from passive large language models to proactive, agentic systems capable of autonomous task execution. As development cycles accelerate, the focus of the open-source community has shifted toward the "harness"—the essential software architecture that provides LLMs with persistent memory, tool-calling capabilities, and environmental awareness. This shift represents a broader industry trend where the model itself is increasingly treated as a commodity, while the surrounding orchestration layer—the infrastructure that governs agent behavior and accountability—becomes the primary source of technical differentiation.
The Rise of Agentic Frameworks and Accountability
Current open-source development is heavily concentrated on ensuring that AI agents function reliably within user environments. One of the most significant challenges in this field is the "black box" nature of agentic decision-making. Tools like agent-inspect have emerged to address this, providing a comprehensive, local-first debugger for TypeScript-based agents. By visualizing execution trees, developers can now track individual tool calls and model responses, pinpointing exactly where a workflow deviates from its intended path. This ability to integrate automated failure triggers into Continuous Integration (CI) pipelines marks a maturation of the AI development lifecycle, moving it closer to traditional software engineering standards.
Data persistence remains another critical hurdle. Most agents operate in a stateless fashion, losing context between sessions. AutoMem addresses this by introducing a persistent memory layer via the Model Context Protocol (MCP). By utilizing graph databases for relationship mapping and vector indices for semantic retrieval, AutoMem allows agents to maintain context across disparate sessions without relying on cloud-based storage. By running entirely within local Docker containers, these systems ensure that proprietary data never leaves the user’s hardware, addressing the primary privacy concerns that have historically hindered enterprise adoption of AI.
The integration of agents into daily workflows has also seen a practical advancement with Tencent’s BrowserSkill. Unlike sandbox-based automation, which often struggles with authentication and complex web navigation, BrowserSkill allows agents to leverage the user’s existing, authenticated browser sessions. This approach balances autonomy with human oversight; the agent operates in a secondary, visible window and only intervenes in active tabs when explicitly prompted. If a task encounters a security barrier like a CAPTCHA or a multi-factor authentication prompt, the system gracefully cedes control to the user, ensuring seamless handoffs.
Hardware Optimization and Model Efficiency
As models grow in complexity, the hardware bottleneck remains a central concern for the developer community. The introduction of frameworks such as Unsloth highlights a push toward higher efficiency in fine-tuning and inference. Unsloth’s methodology, which focuses on dynamic GGUF quantization, enables users to run high-parameter models—such as 27B-class architectures—on significantly reduced VRAM footprints. For instance, the ability to fit large models into 8GB of memory via 1-bit quantization could revolutionize the deployment of edge-based AI.

Complementing this, the llmfit utility provides a standardized way to benchmark local hardware. By analyzing CPU, RAM, and GPU specifications, llmfit ranks available open-source models based on projected performance, allowing users to avoid the time-intensive process of downloading models that exceed their hardware capabilities. This tool is particularly vital given the current trend toward Mixture-of-Experts (MoE) architectures, which require nuanced hardware allocation to be effective.
The Proliferation of MoE Architectures
The open model landscape is currently dominated by the Mixture-of-Experts (MoE) paradigm. Three recent releases underscore the industry’s pivot toward this architecture: Alibaba’s Qwen3.8-Flash-Next, DeepSeek’s V4.1 Flash, and DeepReinforce’s Ornith-1.5.
Qwen3.8-Flash-Next, a 125B parameter model that activates only 6B parameters per token, represents the architecture’s potential for high intelligence at a lower computational cost. Similarly, DeepSeek V4.1 Flash demonstrates the efficiency of aggressively compressed Key-Value (KV) caches, which are essential for maintaining long context windows without overwhelming local system memory. The Ornith-1.5 release from DeepReinforce is particularly noteworthy for its self-improvement loop, where the model iteratively writes and grades its own tasks, signaling a shift toward autonomous model training and refinement cycles.
Industry Consolidation and Regulatory Stance
The infrastructure supporting the open-source AI ecosystem is undergoing significant shifts. The acquisition of OpenRouter by Stripe serves as a bellwether for the industry. OpenRouter acts as a critical gateway, routing over 10 trillion tokens daily across hundreds of models. While the company has pledged to maintain neutrality, the acquisition highlights the increasing reliance of open-source tooling on established financial and technical infrastructure.
Simultaneously, a high-profile debate regarding the speed of AI development has reached the highest levels of the industry. Following the publication of Anthropic CEO Dario Amodei’s essay, "We Must Pace the Frontier," there has been a rare alignment among leaders from OpenAI, Google DeepMind, and xAI, all of whom have suggested that slowing down the development of frontier models may be necessary to ensure safety and alignment. However, this consensus faces political opposition, most notably from the U.S. executive branch, which has emphasized a competitive approach to AI development. This tension between safety-oriented deceleration and competitive acceleration creates a complex environment for the open-source community, which remains the primary venue for democratized, non-proprietary AI advancement.
Operational Best Practices: Memory Management
Technical friction often arises from suboptimal resource management. A common issue among Ollama users is the latency associated with model reloading. By default, Ollama unloads models from GPU memory after five minutes of inactivity. For developers or power users running single-user machines, this results in significant delays when resuming work.
Modifying the OLLAMA_KEEP_ALIVE environment variable allows users to pin models in VRAM for extended periods or indefinitely, depending on the available overhead. While this consumes more power, it eliminates the "cold start" latency that plagues many local AI workflows. This is a microcosm of the broader shift toward treating local AI as a continuous, background service rather than a transient, episodic tool.
Future Outlook and Conference Engagement
The industry is formalizing its approach to agents through major technical gatherings. The upcoming AGNTCon and MCPCon events in Amsterdam and San Jose represent the first concerted efforts to standardize agentic interoperability. These conferences aim to align the disparate protocols currently used for tool-calling and agent communication, which is essential if local AI is to achieve true, cross-platform utility.
As the industry moves into the final quarter of the year, the trajectory is clear: the focus is shifting from "What can a model know?" to "What can a model do?" By wrapping powerful, efficient open-source models in robust, accountable harnesses, the developer community is moving toward a future where AI is not merely a chat interface, but an integrated, automated layer of the digital workspace. The maturation of these tools, combined with improved hardware accessibility and standardized protocols, suggests that the "local AI" revolution is no longer a hobbyist pursuit, but a foundational shift in how computational tasks are managed and executed.
Related posts: