Raising the Code: The Semantic Future of Software Development and the Evolution of the Digital Knowledge Graph

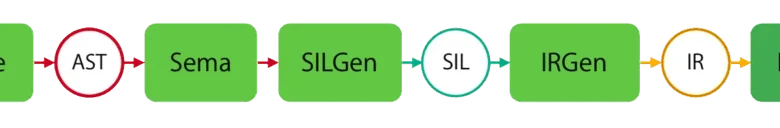
Chris Lattner, a foundational figure in modern compiler infrastructure, frequently describes the role of the LLVM Project as a process of "lowering." This technical concept defines the movement from high-level human-readable abstractions—such as Swift, Objective-C, or C++—down through intermediate representations, ultimately culminating in machine-executable binary code. For decades, the software industry has focused its intellectual energy on perfecting this downward trajectory, ensuring that source code can be translated with maximum efficiency for execution on hardware. However, a growing movement of developers and researchers is now asking a provocative counter-question: if we have perfected the art of lowering code for execution, why haven’t we mastered the art of "raising" code for human and machine understanding?
The current state of software development relies on static analysis and basic syntax highlighting. While tools such as syntax highlighters and structured documentation generators provide a baseline for readability, they remain superficial. They treat code as text to be displayed rather than data to be queried. By applying the principles of the Semantic Web—a vision originally championed by Sir Tim Berners-Lee—to the very structure of source code, the industry may be on the cusp of a shift as significant as the transition from static web pages to data-driven, interactive applications.
A Historical Trajectory: From Web 1.0 to the Semantic Web
To understand the potential of a "Semantic Web of Code," one must examine the evolution of the internet. Web 1.0, which gained prominence in the 1990s, was characterized as a "Web of Documents." It was a decentralized, inter-connected network of static pages where information was largely trapped in human-readable formats. Searching for specific data required manual navigation through directories like Yahoo! or DMOZ.
The early 2000s introduced Web 2.0, the "Social Web." Driven by server-side technologies like PHP and Perl, and eventually, the rise of AJAX, the internet became a platform for dynamic interaction. Developers began creating "mashups," synthesizing data from disparate APIs to create entirely new services. This era proved that when information is exposed through structured endpoints, the potential for innovation increases exponentially.
Web 3.0, or the "Web of Data," solidified this transformation. By adopting standards like the Resource Description Framework (RDF), information became machine-readable. Today, when a user asks a digital assistant like Siri or Google Assistant a factual question, the system does not merely point the user to a search result; it retrieves a specific data point from a structured knowledge graph. This transition from document-centric to data-centric architecture is the missing link in current software development workflows.
The Current Bottleneck: Code as an Unstructured Document
Despite the sophistication of modern development environments, the way we manage source code repositories remains surprisingly primitive. On platforms like GitHub, the "README" file acts as a digital storefront, mirroring the static, hand-coded personal websites of the mid-1990s. While tools like tree-sitter and semantic-aware indexing have improved the ability to navigate declarations, the fundamental limitation persists: code is largely treated as unstructured text.
A developer looking for a specific function, its requirements, and its dependencies must manually parse documentation, which is frequently outdated or incomplete. There is no standard, universal "query language" for the global corpus of open-source code. We are currently operating in an "AltaVista era" of code discovery, where we rely on full-text search strings rather than semantic, relational queries.
The RDF Framework: A Blueprint for Semantic Code
At the core of the proposed shift is the Resource Description Framework (RDF). RDF allows for the representation of information in "triples"—subject, predicate, and object. By defining an ontology for programming languages, developers can treat a function as a "Subject," its "Returns" value as a "Predicate," and the data type as an "Object."
By utilizing tools such as SwiftSyntax and SwiftSemantics, developers can parse source code into an Abstract Syntax Tree (AST) and then map those nodes into RDF-compliant formats like JSON-LD or Turtle. Once code is mapped in this way, it can be stored in graph databases such as Neo4j or queried using SPARQL.
For example, a developer could execute a query to find all functions in a codebase that return a specific structure, regardless of the function name. This moves the interaction from a "find-in-files" search to a structural analysis of the codebase, allowing for automated validation of architecture, dependency management, and consistency checks that are currently impossible through text-based search.
Broader Implications: FaaD and the Future of AI
The implications of this transition extend into the concepts of "Functions as a Dependency" (FaaD) and automated code generation. Currently, modern package management involves importing entire libraries, even when only a fraction of their functionality is required. A semantic understanding of code could allow compilers to extract only the specific functions necessary for a task, effectively "tree-shaking" at a logical rather than just a syntactic level.
Furthermore, the rise of Artificial Intelligence (AI) in software development—exemplified by models like OpenAI’s GPT series—is currently limited by the fact that these models often treat code as text. If these models were trained on a structured, semantic knowledge graph of code, their ability to generate accurate, functional, and verifiable code would improve by orders of magnitude. Because the rules of programming are "codified," an AI that understands the semantic relationships within a language can verify its own output by attempting to compile and run the generated code against a set of semantic constraints.
The Professional Responsibility
The history of technology is replete with examples of professional groups that were slow to adopt the very innovations they helped create. Richard Hamming, in The Art of Doing Science and Engineering, famously noted that "the shoemaker’s children go without shoes." While software engineers have built the tools that transformed healthcare, law, and finance through automation and data-driven analysis, they have been surprisingly conservative in applying those same techniques to their own craft.
The industry stands at a crossroads. As software grows in complexity, the traditional manual approach to code management and discovery is becoming a bottleneck to further progress. By shifting the paradigm from lowering code for execution to raising code for semantic understanding, the development community has the opportunity to create a new layer of infrastructure—a global knowledge graph of software—that could redefine the efficiency, reliability, and capability of programming for the next generation. The future of software is not just in writing more lines of code, but in creating a connected, machine-understandable ecosystem where information is as accessible as the logic that powers it.
Related posts: