AWS Weekly Roundup: Modernizing Migrations, Enhancing Agent Runtimes, and Scaling Cloud Infrastructure

Migrating legacy data infrastructure has historically presented organizations with a challenging logistical hurdle, characterized less by the complexity of the destination technology and more by the operational friction of the move itself. Traditional transitions—such as shifting enterprise Apache Hive tables to Apache Iceberg—frequently required weeks or months of intensive engineering effort, custom data pipeline development, and scheduled system downtime.
Recent updates from Amazon Web Services (AWS) aim to fundamentally alter this paradigm. By focusing on non-disruptive modernization patterns, AWS has introduced a suite of tools designed to streamline data lake migrations, accelerate database operations, and optimize artificial intelligence agent architectures without requiring active workloads to halt.
Streamlining Data Migrations: From Apache Hive to Apache Iceberg
The financial and operational cost of adopting modern data architectures is heavily weighted toward migration friction. Addressing this systemic challenge, Amazon S3 Tables introduced a managed migration capability designed to transition Apache Hive tables registered in the AWS Glue Data Catalog directly into Apache Iceberg format.
Previously, engineering teams had to provision separate compute resources, construct custom ETL pipelines, and carefully orchestrate cutover windows to prevent data drift or application downtime. The new managed workflow reduces this complex multi-step process into a streamlined three-phase procedure: initialization, incremental synchronization, and final cutover.
During the migration lifecycle, the source data store remains fully writable. The system validates the source architecture, generates a comprehensive compatibility report covering every object in scope, and executes incremental sync operations that copy only modified data. Consequently, production systems can continue normal operations right up to the final minutes of the cutover window. Once migrated, tables can be queried using high-performance engines such as Amazon Athena, Amazon SageMaker Unified Studio, or any analytics platform that supports the open Iceberg REST API.
Priced strictly on the volume of data copied with no additional conversion fees, this capability launched across ten AWS Regions, supporting objects utilizing S3 Intelligent-Tiering without altering their underlying storage classes. Industry analysts note that removing the friction of format modernization accelerates enterprise adoption of open-table formats, which offer superior performance and governance for large-scale data lakehouses.
Advancing AI Agent Architecture: The New AgentCore Runtime
As artificial intelligence agents transition from experimental proofs of concept to core enterprise workloads, infrastructure efficiency and predictable latency have become paramount. AWS responded to these demands by rolling out general availability for the new Amazon Bedrock AgentCore Runtime, introducing structural changes to memory management and container initialization.
Under legacy agent runtime models, memory allocations remained tied to peak usage thresholds throughout a session, resulting in inefficient resource consumption and elevated costs. The new AgentCore Runtime implements a dynamic memory paging mechanism. Sessions begin with minimal memory footprints, page in additional resources strictly on demand, and immediately return cold memory back to the infrastructure pool. Organizations thus pay strictly for the computational resources actively consumed.
Furthermore, the runtime tackles the persistent engineering challenge of cold-start latency. Traditionally, scaling up agent instances required provisioning environments dynamically, with latency increasing linearly as container image sizes grew. The new architecture prepares the execution environment once, captures a snapshot, and rapidly restores that snapshot for every newly instantiated instance.
Internal AWS benchmarking data highlights the efficacy of this approach. For container images ranging from 200 MB to 2 GB, the P75 cold-start latency on the V2 runtime remained consistently anchored at approximately 2 seconds. By comparison, the legacy runtime exhibited sharp performance degradation, with cold starts climbing from 5.4 seconds for smaller images to nearly 30 seconds for 2 GB packages. While the per-unit compute rate for the V2 platform is marginally higher, the drastic reduction in total gigabyte-hours is projected to lower overall billing for most enterprise deployments.
To adopt the new runtime, developers configure the platformVersion parameter to V2 during resource creation or update cycles. Because the infrastructure must generate and validate execution snapshots, update operations require several minutes to complete. Additionally, container images must signal successful initialization via a /ping health check endpoint within a strict 120-second window.
Enterprise Database and Streaming Enhancements
Beyond data lakes and generative AI infrastructure, AWS deployed critical performance and scalability upgrades across its core database and event-streaming portfolios.

Amazon DynamoDB introduced native support for bulk item ingestion, allowing organizations to load line-delimited DynamoDB JSON or Amazon Ion files directly from Amazon S3 into pre-existing tables as a managed, asynchronous operation. Each individual record within the ingestion file can incorporate customized condition expressions, permitting a single bulk file to seamlessly combine plain inserts, exclusive creations, and version-guarded updates.
Executing via dedicated system capacity rather than standard provisioned throughput, the bulk put feature significantly reduces the financial cost compared to equivalent per-request API calls. For time-sensitive migrations, an Accelerated tier accommodates deadline-bound workloads; illustrative benchmarks published by the AWS Database engineering team demonstrate the capacity to load 100 million 1 KB items in under one hour. Database administrators must note, however, that canceling an active bulk-load job does not automatically roll back items already written to the target table.
In the realm of event-driven architectures, AWS Lambda announced native queue consumption support for Apache Kafka, utilizing Kafka share groups across self-managed clusters and fully managed streaming services such as Confluent Cloud. Historically, classic consumer group architectures capped event-processing parallelism strictly to the total partition count of a given Kafka topic.
The new queue mode decouples processing parallelism from partition counts by distributing records from a single partition across numerous concurrent Lambda invocations. Because this operational mode trades strict partition-level ordering for at-least-once delivery guarantees, developers must ensure their serverless functions are engineered to be idempotent.
Hybrid Connectivity and Security Compliance
Network architecture and security posture management also received substantial updates, highlighted by expanded hybrid cloud connectivity options and automated asset inventorying.
AWS announced the preview of AWS Interconnect—last mile, developed in strategic collaboration with Equinix. This managed connectivity service enables enterprises to establish private, highly resilient network connections from Equinix’s global footprint of 282 data centers directly into AWS infrastructure, eliminating the traditional operational overhead of ordering physical cross-connects or manually configuring BGP routers and VLANs.
The service features quad-redundant capacity spanning two physical data center locations and four distinct network paths, backed by a 99.99% availability Service Level Agreement (SLA) and default MACsec encryption. The initial preview phase supports the San Jose and Northern Virginia metropolitan areas, offering 1 Gbps connections at zero additional charge during the evaluation period.
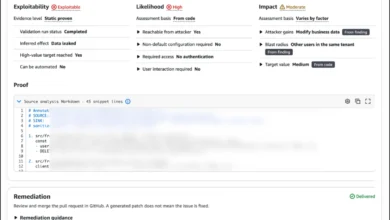
On the security front, AWS Security Hub integrated automated Software Bill of Materials (SBOM) inventory tracking across organizational computing resources. Security teams can now comprehensively view every installed software package across Amazon EC2 instances, Amazon ECR container images, and AWS Lambda functions directly within the Security Hub console.
Rather than requiring custom scanning pipelines, the inventory aggregates SBOM data automatically generated by Amazon Inspector, displaying precise package versioning and asset blast radii. This automated visibility provides critical telemetry for vulnerability management, significantly shortening response times when widely utilized open-source libraries are impacted by newly disclosed security flaws.
Community Milestones and Ecosystem Outlook
As the cloud computing sector looks toward the closing weeks of the calendar year, the technical community is preparing for the upcoming AWS re:Invent conference, scheduled to take place in Las Vegas from November 30 to December 4. With the official event catalog live and reserved seating open, developers and enterprise architects are actively finalizing schedules across technical tracks covering generative AI, serverless engineering, and data infrastructure modernization.
Concurrently, regional AWS Community Days—volunteer-led conferences organized by local technology advocates—continue to foster peer collaboration worldwide, with upcoming gatherings scheduled in Belém (Brazil), Akita (Japan), and Port Harcourt (Nigeria).
These architectural refinements underscore a broader industry trend: cloud providers are increasingly prioritizing operational continuity. By engineering modern migration pathways, elastic serverless runtimes, and non-disruptive data ingestion frameworks, AWS is actively working to minimize the engineering tax traditionally associated with cloud adoption and infrastructure evolution.
Related posts: